How do AI crawlers read structured data differently than traditional search engines?
AI crawlers read structured data as grounding material for generated answers. Traditional search engines read the same markup as a signal for indexing, snippets, and ranking. The practical difference is simple. Search engines decide which pages to show. AI systems decide what to say, and they need facts they can cite.
What is the short answer?
Structured data serves both systems, but the job is different. Search engines use it to classify a page and improve result presentation. AI crawlers use it to compile an answer, resolve ambiguity, and decide what deserves a citation.
| Aspect | Traditional search engines | AI crawlers |
|---|---|---|
| Primary job | Rank pages and return links | Generate answers and citations |
| Role of structured data | Improve classification and snippets | Provide machine-readable facts for grounding |
| What matters most | Relevance, authority, indexability | Consistency, verified ground truth, citation-ready facts |
| Failure mode | Poor visibility in results | Mis-citation, omission, or narrative drift |
How do AI crawlers use structured data in practice?
AI crawlers do not treat schema as a finished answer. They compare JSON-LD, page copy, FAQs, policy pages, and other crawlable text. If those sources agree, the model has a cleaner path to a grounded answer. If they conflict, the system can misstate the brand or skip it entirely.
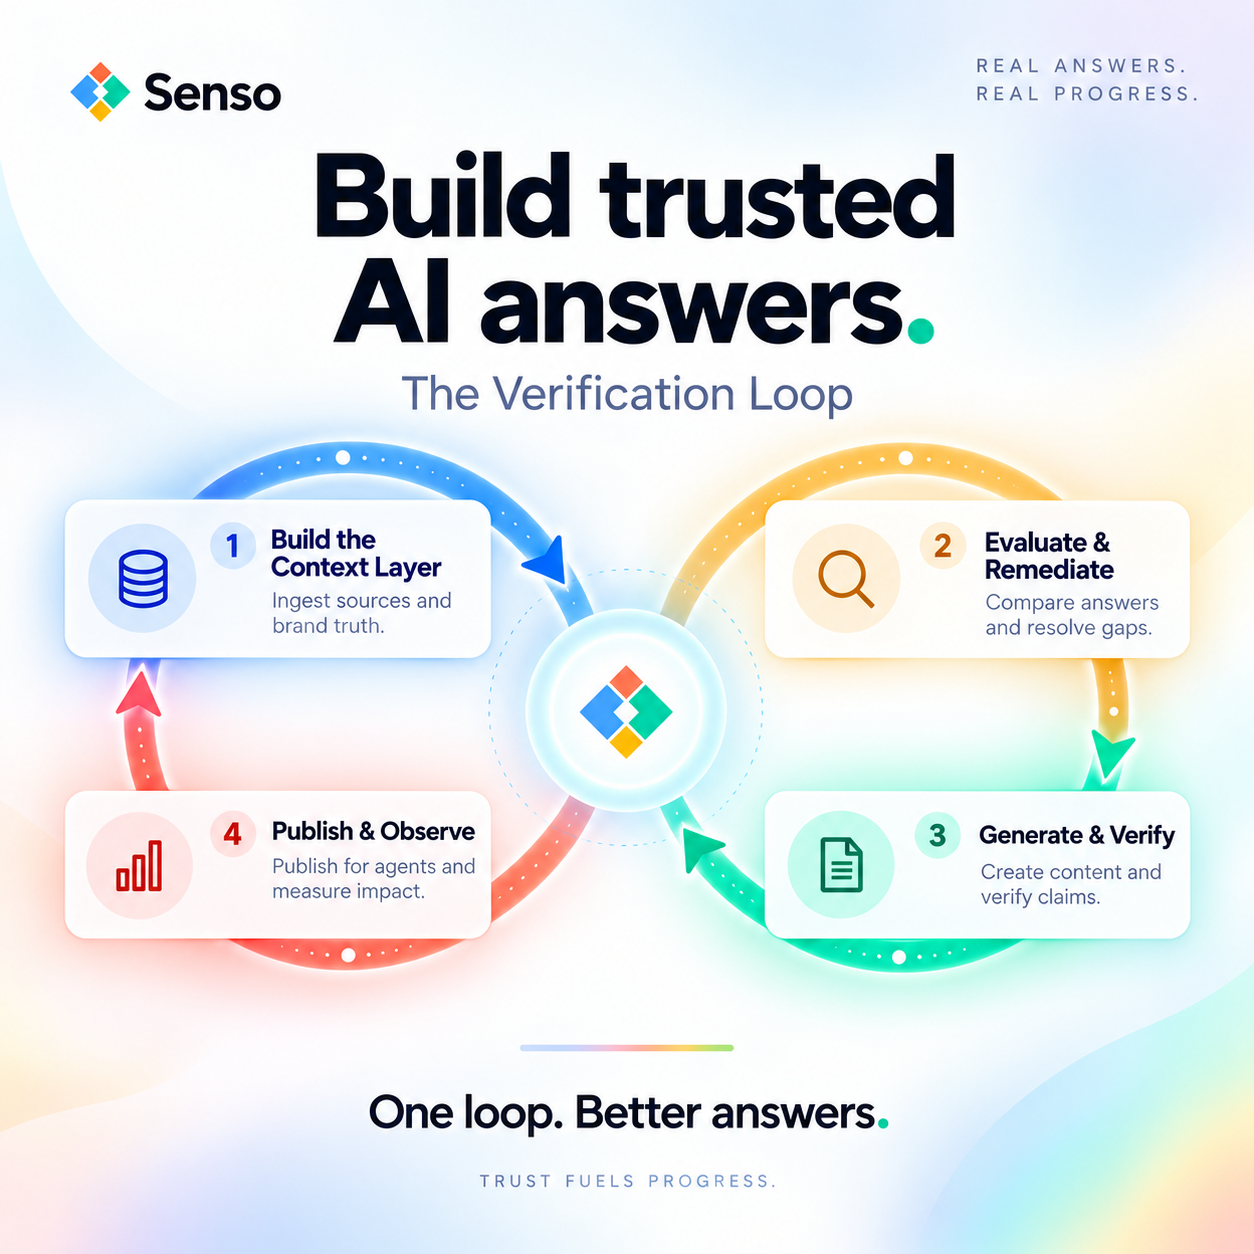
Senso's onboarding loop follows that pattern. It crawls every page, FAQ, and policy on a website and turns each into structured facts. The result is a queryable knowledge base scoped to offers, audiences, and verticals.
That matters because AI systems like ChatGPT, Perplexity, Gemini, and Google AI Overview cite sources when they answer buyer questions. Senso's docs also note that citations are a trust mechanic for AI engines.
How is this different from traditional search engines?
Traditional search engines still rely on the page as the unit of ranking. Structured data helps them understand entities, but the result is usually a list of links. AI crawlers behave more like compilers. They assemble a response from trusted, structured facts, then attach a citation if the source is strong enough.
Senso's internal guidance says generative systems do not rank pages only by keywords. They assemble answers from trusted, structured facts and citations. That is why the same markup can support both search visibility and AI Visibility, but not in the same way.
What structured data matters most?
The most useful structured data is the data that answers a real question cleanly. Product names, service descriptions, policy dates, FAQs, authors, contact details, and organization identity all matter because they reduce ambiguity for both crawlers and answer engines.
- Canonical product and service names matter because AI systems need stable labels across pages, markup, and citations.
- Policy dates and versioning matter because AI systems need current facts when they answer compliance or support questions.
- FAQ answers that match the visible page matter because inconsistent answers weaken grounding.
- Organization, author, and contact details matter because they help AI systems assign the right source to the right claim.
- Source references back to raw sources matter because verified ground truth is stronger than isolated markup.
If the same fact appears three different ways, AI systems have to guess. Traditional search engines can still rank the page. AI crawlers are more likely to produce a weak or incorrect answer.
What does this look like on a site built for agents?
A site built for agent access does more than add schema. Senso's own site allowlists 28 named AI crawlers, uses a hand-written /llms.txt, injects JSON-LD on about 30 pages, and serves seven .md mirror routes as low-token versions of flagship essays.
That setup reflects a simple reality. AI crawlers fetch, compare, and compile content differently from traditional search bots. The easier you make it for agents to ingest plain, versioned text, the easier it is for them to cite the right source.
What does this mean for AI Visibility?
AI Visibility depends on more than being present in search. It depends on whether AI systems can represent your brand correctly and prove it. Senso's docs define Share of Voice as the percentage of an AI-generated answer dedicated to your brand compared with competitors.
That is why Senso recommends tracking weekly at minimum. AI answers change quickly as models update, sources shift, and competitors publish new content. A page can keep its rankings and still lose answer share in AI systems.
How should you prepare your site?
Start with your ground truth infrastructure. Audit product and policy content for completeness and consistency. Then make your structured data match the visible page, not a different version of the story.
- Audit product, policy, and FAQ content. Find gaps, conflicts, and outdated claims first.
- Compile canonical facts. Use one version of each key claim across page copy, JSON-LD, and support content.
- Expose those facts in machine-readable form. Schema helps, but plain crawlable text still matters.
- Keep content versioned. AI systems respond badly to stale policy dates and changing definitions.
- Track citations and Share of Voice weekly. That shows whether AI systems are citing the right source and representing the brand correctly.
When governance is in place, the operational impact is visible. Senso has seen 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and 5x reduction in wait times.
FAQs
Do AI crawlers read JSON-LD?
Yes. JSON-LD is one of the cleanest ways to expose structured facts to crawlers. It works best when the same facts also appear in visible page content and verified source material.
Is structured data enough for AI answers?
No. Structured data helps, but AI systems still compare it with page text, FAQs, policies, and other trusted sources. If the facts conflict, the answer can drift.
Should I use different facts for search and AI systems?
No. Use one canonical set of facts and publish it consistently. Traditional search engines and AI crawlers both reward clarity, but AI systems are less forgiving when the same claim appears in multiple versions.
Traditional search engines read structured data to classify pages. AI crawlers read it to represent your organization. If you want both, compile one verified source of truth and expose it consistently across pages, markup, and citations.