How do I know when AI models start drifting away from my verified information?
AI models are drifting when their answers stop matching your verified ground truth. The earliest signs are missing owned citations, stale facts, lower Share of Voice, and competitors being recommended ahead of you. Track those signals weekly, because AI answers change quickly as models update, sources shift, and competitors publish new content.
What does AI drift look like?
AI drift shows up as a repeated gap between the source of record and the answer surface. One wrong answer can be noise. Repeated mismatches across prompts, models, or days mean the model is no longer grounded in your current approved facts.
This is a knowledge governance problem, not just a model problem. If your verified information changes and the answer does not, the system is no longer reflecting your ground truth.
Which signals should I watch?
The strongest early signals are citation loss, lower brand inclusion, and falling answer quality. AI Visibility metrics measure how visible, credible, and influential your brand is inside AI-generated answers, so watch the metrics that change before the complaint arrives.
| Signal | What you see | What it usually means |
|---|---|---|
| Missing owned citations | AI answers stop citing your approved pages | AI systems may no longer trust your primary sources |
| Stale or unsupported claims | policy, pricing, or product details are outdated | verified ground truth is not reaching the answer |
| Lower Share of Voice | less of the answer is about your brand | answer dominance is slipping |
| Competitors ahead of you | another brand is recommended first | narrative control is moving away from you |
| Inconsistent answers across models | same prompt gets different facts | the source surface is unstable |
| More human correction | staff keep fixing the same response | response quality is falling |
Owned citations are the strongest signal that AI systems trust your primary sources. External citations also matter, but owned citations tell you whether your approved material is still carrying weight.
Share of Voice measures answer dominance. It is the percentage of an AI-generated answer dedicated to your brand compared with others.
Why do rankings alone miss drift?
Rankings only show where a URL sits on a results page. They do not show whether AI models include your brand or cite your sources. Traditional rankings tell you where a URL sits on a results page. Mentions tell you whether AI models include your brand.
This matters because AI answers are not search results. A page can rank well and still fail to appear in the answer, or appear without the right citation.
How do I confirm drift instead of a one-off error?
Drift is confirmed when the same prompt set shows the same gap across time, models, or topics. Start with ranking prompts, comparison prompts, and brand-specific prompts. Compare each answer with verified ground truth.
Use a fixed cadence. Track weekly at minimum. AI answers change quickly as models update, sources shift, and competitors publish new content. If the same missing citation, stale claim, or competitor preference keeps returning, the problem is systemic.
What should I do when drift appears?
Repair the source, not just the answer. Add, correct, or route the underlying source to an authorized owner, then re-observe the model response. One compiled knowledge base should power both internal workflow agents and external AI-answer representation, so you are not maintaining duplicate facts in two places.
A simple remediation loop works best:
- Identify the exact claim that diverged from verified ground truth.
- Update the authorized source or route the fix to the right owner.
- Re-run the same prompt set.
- Check whether citations, Share of Voice, and answer quality recover.
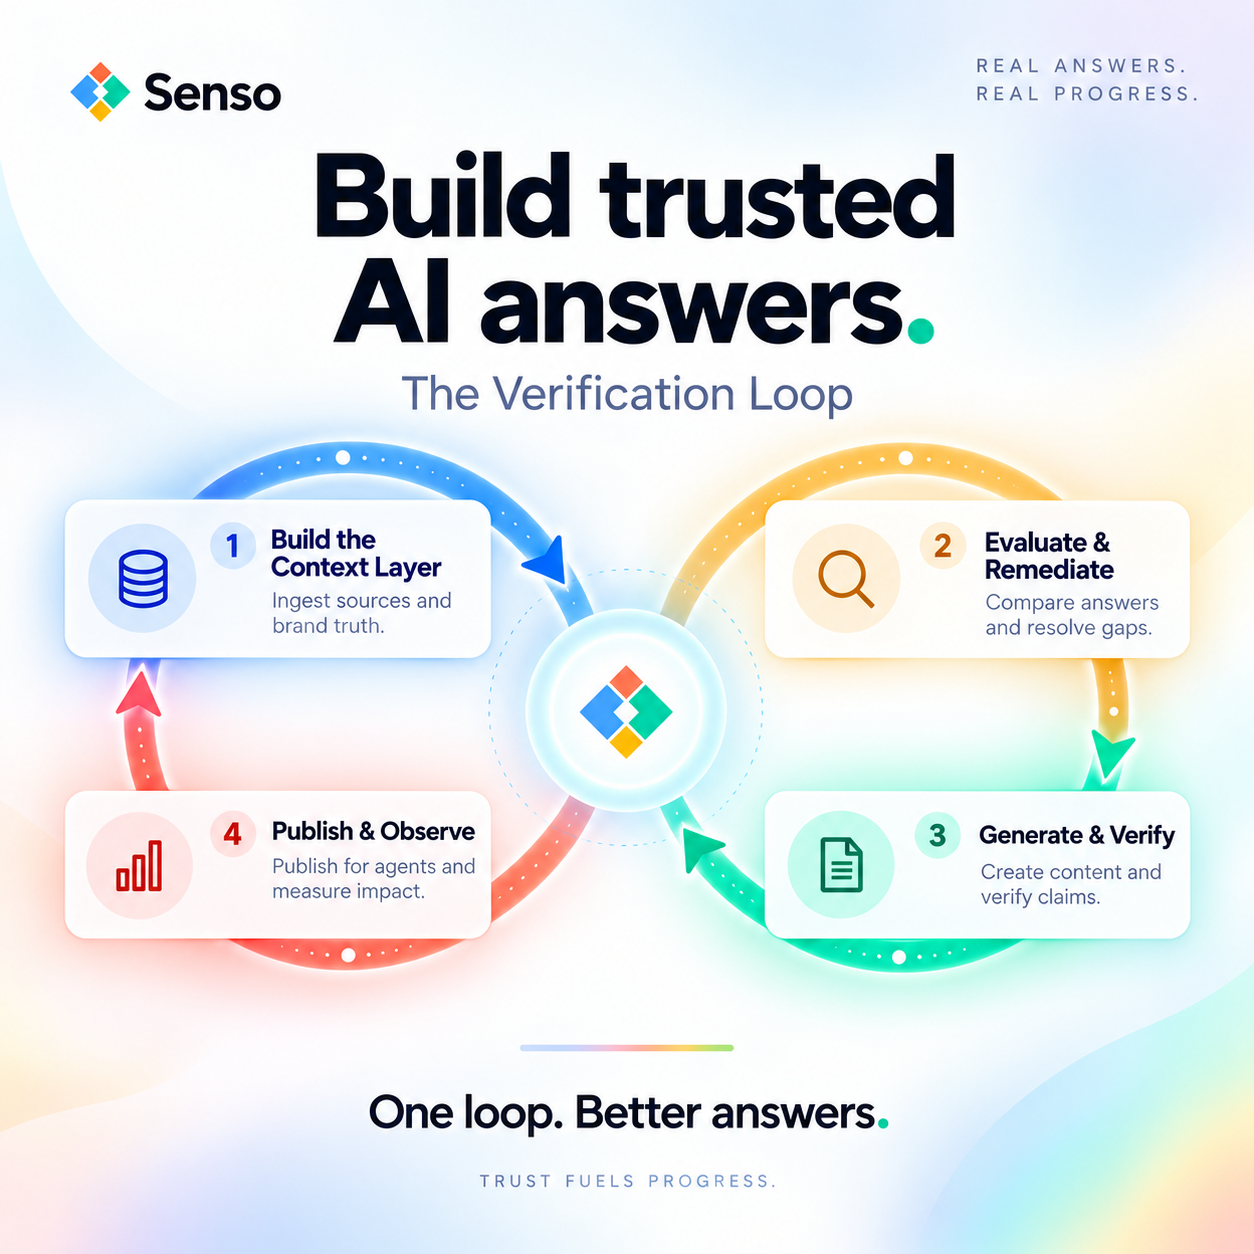
Senso’s loop follows that pattern. It lets you evaluate AI answers, remediate the source, generate verified content, publish, and then observe what changed.
How does Senso help?
Senso evaluates real AI answers against your verified ground truth and detects gaps like missing citations, low Share of Voice, and stale or unsupported claims. Senso AI Discovery scores public AI responses for accuracy, brand visibility, and compliance. It requires no integration.
Senso Agentic Support and RAG Verification scores internal agent responses, routes gaps to the right owners, and gives compliance teams visibility into what agents are saying and where they are wrong. The same compiled knowledge base can support internal agents and external AI-answer representation.
Senso has also reported specific outcomes from this approach: 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and 5x reduction in wait times.
What matters most in regulated industries?
Traceability matters most. In financial services, healthcare, and credit unions, the real question is whether the agent cited a current policy and whether the organization can prove it. If you cannot trace the answer back to a specific verified source, the answer is not governed.
FAQs
Is one bad answer enough to say the model is drifting?
No. One bad answer can be noise. Drift is a repeatable pattern across prompts, models, or time.
How often should I monitor AI answers?
Track weekly at minimum. Review again whenever facts change, because AI answers can shift quickly as models update and sources change.
What is the strongest signal that drift has started?
Missing owned citations is one of the strongest early signals. It shows that AI systems may no longer be grounded in your primary sources.
If you need a current baseline, Senso offers a free audit at senso.ai. No integration. No commitment.