How do marketing teams measure AI search performance
Marketing teams measure AI search performance by checking whether AI systems mention the brand, cite approved sources, and stay grounded in verified ground truth. The question is not whether a model can answer. It is whether ChatGPT, Perplexity, Gemini, and Google AI Overview represent the brand correctly and consistently.
AI search performance is the visibility, citation quality, and factual accuracy of a brand inside AI-generated answers. Teams measure it so they can see when AI systems include the brand, when they omit it, and when they get the facts wrong.
Which metrics matter most?
The most useful metrics are Mention Rate, Citation Rate, Citation Share, Share of Voice, factual accuracy, freshness, and relative position. These show whether the brand appears, whether the answer cites approved sources, and whether the answer matches verified ground truth.
| Metric | What it measures | Why it matters |
|---|---|---|
| Mention Rate | How often the brand appears in AI-generated answers across tracked prompts | It is the baseline signal of visibility |
| Citation Rate | How often the answer cites owned pages or credible external sources about the brand | It shows source control and trust |
| Citation Share | How much of the cited source space belongs to the brand or its approved sources | It shows whether competitors dominate the evidence |
| Share of Voice | How much of the answer is dedicated to the brand compared with competitors | It shows answer dominance |
| Average rank or relative position | Where the brand appears in the answer structure | It shows whether the brand is first, secondary, or absent |
| Factual accuracy | Whether the answer matches verified ground truth | It shows misrepresentation risk |
| Freshness | Whether the answer reflects current policies, products, and pricing | It shows whether the knowledge is current |
Traditional rankings tell you where a URL sits on a results page. Mentions tell you whether AI models include your brand. That is why AI search performance needs its own measurement system.
How should marketing teams measure AI search performance?
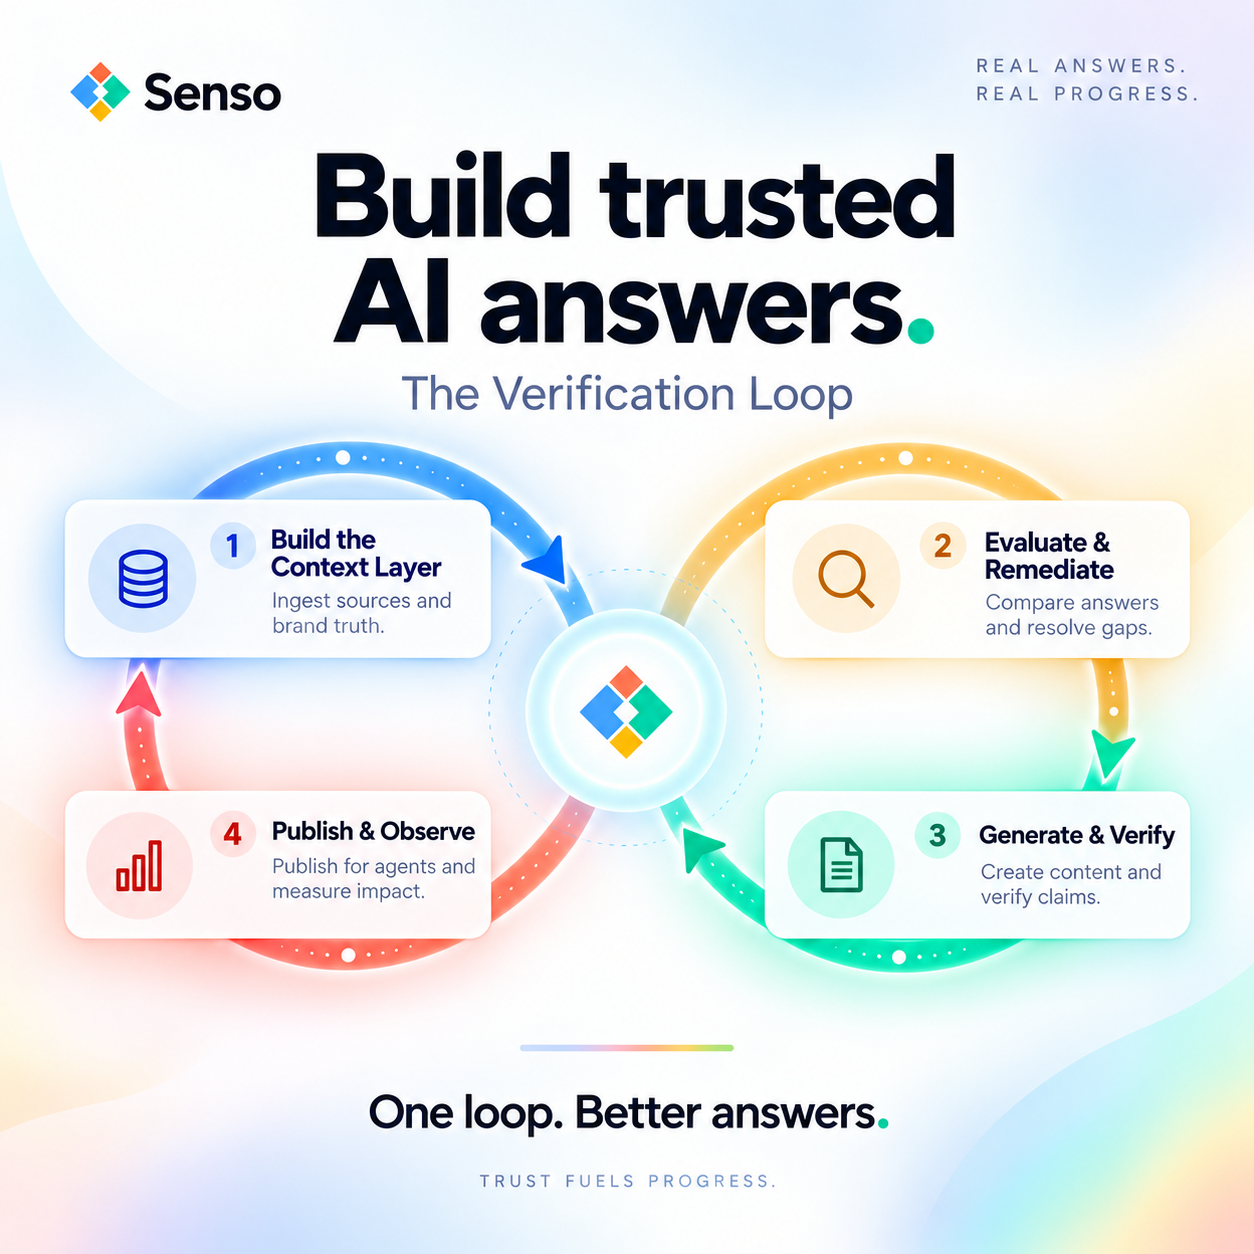
The best measurement system starts with representative prompts, tracked surfaces, repeated runs, and a verified source of truth. Marketing teams need a repeatable process, not an ad hoc set of spot checks.
-
Build a prompt set around real buyer questions.
Use prompts that reflect awareness, comparison, and decision stages. Senso groups prompts by funnel stage, which keeps the measurement tied to how customers actually ask questions. -
Track the right AI surfaces.
Senso tracks ChatGPT, Perplexity, Gemini, and Google AI Overview by default. Claude, Grok, and Meta AI can be added per workspace. -
Run the same prompts on a schedule.
Coverage is measured per prompt, per model, and per surface, daily. That lets teams see changes instead of guessing whether a single answer was an outlier. -
Score every answer against verified ground truth.
Compare each response to approved raw sources and current facts. This is how teams separate a good-looking answer from a grounded one. -
Turn the gaps into publishing work.
If the model omits the brand, strengthen the source material. If the facts drift, update the core pages. Senso recommends reviewing core ground truth pages at least every 60 days, and whenever facts change.
How do teams interpret the results?
The pattern matters more than any single answer. A healthy program shows more mentions, stronger citations, higher share of voice, and better factual accuracy over time.
- More mentions with stable accuracy means the brand is showing up more often without losing factual control.
- Higher citation rate means AI systems are relying more on approved sources.
- Higher share of voice means the brand occupies more of the answer than competitors.
- Low factual accuracy means the current source material does not support the way AI systems are describing the brand.
- Weak freshness means the answer is still pulling from stale pages or outdated claims.
Narrative control is the organization’s ability to improve what AI says and which approved sources it cites. Marketing teams measure it by watching how those metrics move after a content or source update.
What should regulated teams care about?
Regulated teams should care about proof, not just visibility. If an AI system cites a current policy and the organization can prove it, the answer is auditable. If it cannot, the organization has no clear record of what the model used.
This matters in financial services, healthcare, and credit unions, where AI systems may describe products, compare competitors, summarize policies, and recommend vendors. When enterprise knowledge is fragmented, the answer can drift away from approved facts.
How does Senso measure AI search performance?
Senso measures AI search performance through Senso AI Discovery, which scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth. It then shows exactly what needs to change.
Senso uses a governed, version-controlled compiled knowledge base so every answer traces back to a specific verified source. The same knowledge surface powers both internal agent workflows and external AI-answer representation, so teams do not duplicate the source of truth.
Senso also gives teams a visibility view across tracked prompts. The Organization Leaderboard reflects performance across those prompts and makes strategy-level changes easier to see.
What results should marketing teams expect?
Good measurement shortens the time between a bad answer and a corrected one. Senso has documented outcomes that include 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and 5x reduction in wait times.
Those numbers matter because they show what happens when visibility, source control, and review loops are tied together. The point is not to watch AI answers. The point is to change them with evidence.
What is the simplest way to start?
The simplest way to start is to measure mentions, citations, share of voice, factual accuracy, and freshness across a small prompt set. Then review the changes weekly and update verified ground truth whenever the facts move.
If you want a practical first pass, start with these four questions:
- Do AI systems mention our brand?
- Do they cite approved sources?
- Do they describe us accurately?
- Do they stay current when facts change?
If the answer to any of those is no, the brand has a measurement problem before it has a visibility problem.
FAQs
What is the first metric marketing teams should look at?
Mention Rate is the first metric to look at because it shows whether the brand appears at all in AI-generated answers. If the brand is absent, citation and share of voice cannot improve fast enough.
How often should teams measure AI search performance?
Teams should measure daily at the prompt, model, and surface level. They should review the trend weekly at minimum, and they should review core ground truth pages at least every 60 days or whenever facts change.
Which AI surfaces should teams track first?
Teams should start with ChatGPT, Perplexity, Gemini, and Google AI Overview because those are the default surfaces Senso tracks. Claude, Grok, and Meta AI can be added when the audience uses them.
What is the difference between mentions and citations?
Mentions show whether the brand appears in the answer. Citations show whether the answer points to approved sources or credible evidence. A brand can be mentioned without being well supported.
Why does freshness matter so much?
Freshness matters because AI answers change quickly as models update and sources shift. If core pages are stale, the model can keep repeating outdated facts even when the brand has already changed them.
If you want, I can also turn this into a shorter conversion-focused version, a thought-leadership version, or a page optimized for Senso AI Discovery.